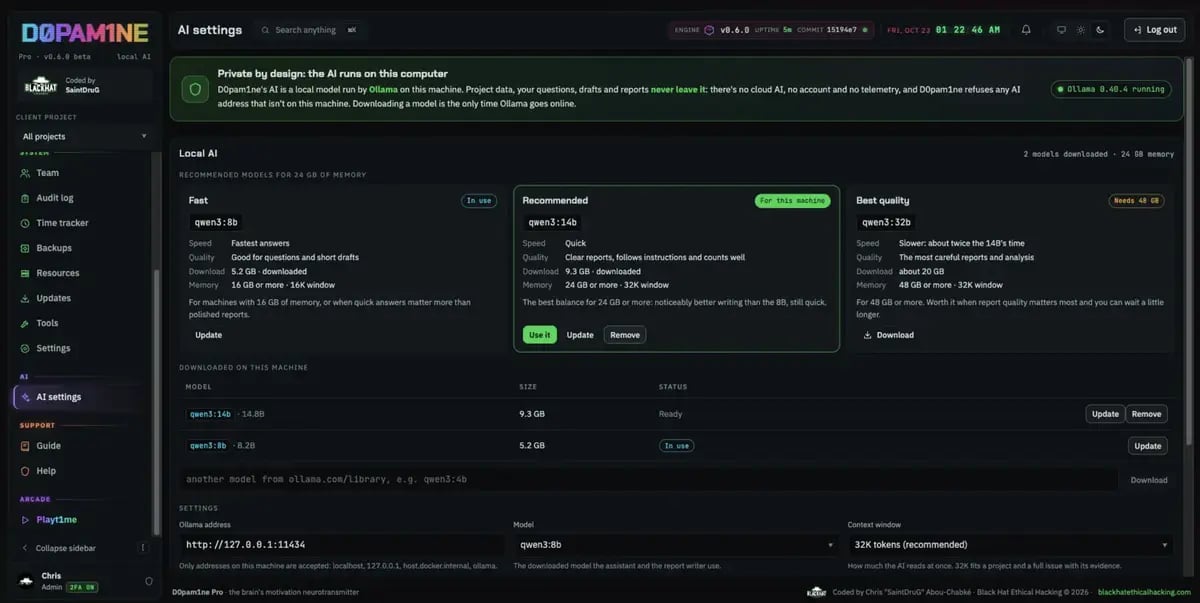
AI settings: private by design, with recommended local models
Private by design
The AI module is “text in, text out”: it has no access to the scanners, the network (beyond the local Ollama) or the database. It only ever receives the read-only context the server assembles, and its output is stored as a draft you accept. The default model isqwen3:14b; the settings page recommends models for your available memory and manages what is installed.
What it does
- Triage findings in Needs Review, with a suggested verdict and confidence.
- Draft issue sections (description, risks, technical description, steps, recommendations) from the evidence.
- Explain impact, remediation and severity, and write executive summaries.
- Answer questions about the project through the Ask AI assistant.
What it will not do
It never runs or plans attacks, writes exploits, or picks new targets. It states only facts that are in its context, quotes the project’s real numbers rather than estimating, and never invents hosts, versions, payloads or CVEs. A verdict it suggests never changes a finding’s status on its own; you accept it.Because the model stays loaded between questions and runs on your hardware, the first question after a cold start is slower while the model warms up. Thinking models answer chat without thinking and think only when drafting a report.